Technical SEO Now Includes AI Crawlers
AI crawlers pull content for LLMs and answer engines, a different purpose than Googlebot. Blocking AI crawlers won’t impact how Google ranks you, but they will determine if your content is referenced in LLM search results and AI Overviews. Because they’re powered by search engines, GEO is an extension of SEO. The same site architecture is helpful for both.
“From a mindset perspective it’s realising that the field is changing drastically and what was true before is not true anymore — Abhishek Iyer, founder of ACME.BOT”
A few things to note:
- LLMs use AI crawlers to follow links, feed them data, and power AI real-time assistants, not index for search results.
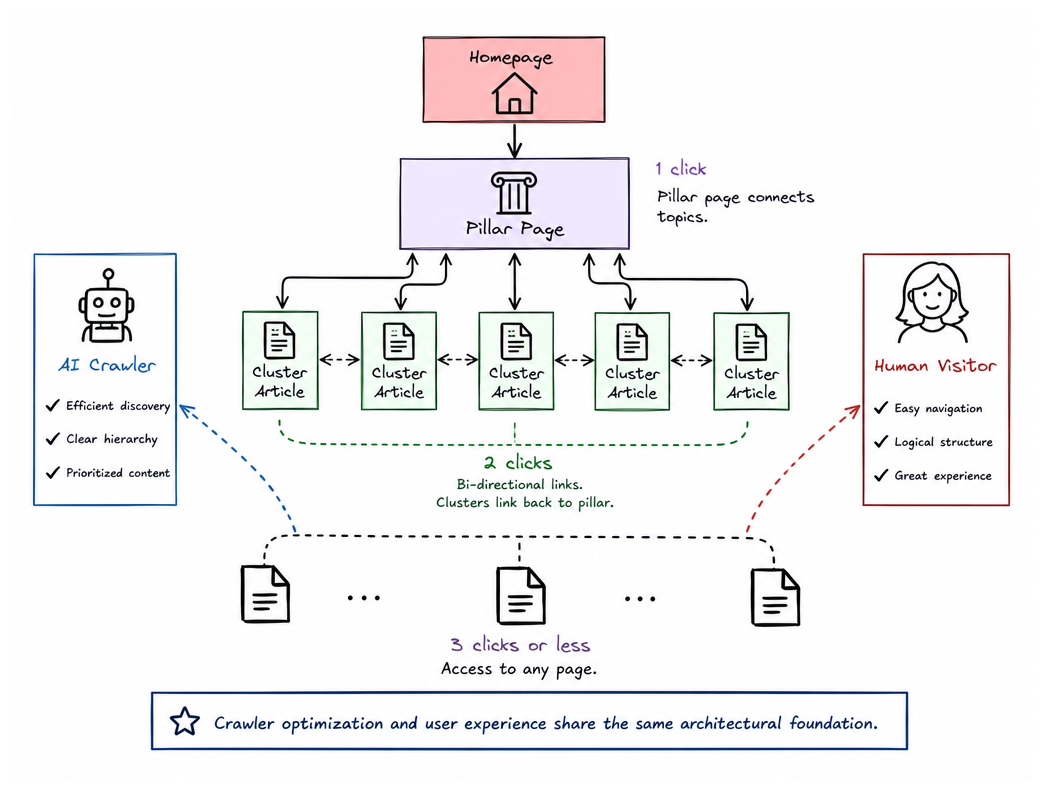
- Both AI crawlers and Googlebot will benefit from pillar-cluster structures, descriptive URLs, and context-rich internal linking.
- You don’t need to have different strategies for each. One strong architecture can be leveraged for both answer engines and search.
That’s the, shift. Same foundation, double the reach. The architecture moves that follow show you how.

The Key Site Architecture Moves That HELP Crawlers & Users
There are four site design moves that benefit users and search engine crawlers with NO trade-offs: – pillar-cluster topology which promotes high-priority pages to no more than 3 clicks away – keyword-rich but clean URLs that help searchers and crawlers with click-through and crawlability – contextual links between site pages that make the search intent of your website obvious to crawlers – well set-up XML sitemap combined with llms.txt file that helps AI solutions find your authoritative content.
1. Pillar-cluster topology
Pick one page (one level below your homepage) to be your pillar page, and make cluster articles that all link back to it. This approach creates topical authority and keeps the pages that you want to be most important within 3 clicks of a user/objective entering your site. It’s a crawling and people-friendly setup that’s become the standard for 2026.
2. Include keywords in short, snappy URLs
URLs that contain target keywords receive 45% higher click-through rates and help crawlers easily navigate your site.. Don’t use deeply nested paths. Important pages should be on shallow paths — these are easier for users to remember and find.
3. Contextual internal links
Contextual links within your page content are more valuable than boilerplate or navigation links. Ensure that each page has at least one incoming link, otherwise it becomes an orphan. The way you link your pages helps search engines understand which pages are most important to you.
4. Sitemap and llms.txt
Add an XML sitemap to your robots.txt file that also includes freshness signals via llms.txt file that explains your business and lists your most authoritative pages so AI systems know where to start looking.
It’s like having a well-labelled library. AI and humans navigate by signposts, not guesswork. They use signposts and markers to “get to” where they want to go.
The payoff: descriptive URLs and three-click depth assistance that help crawlers also curtail bounce for human visitors. You’re not sacrificing one for the other — they’re served by the same move.
Common architecture problems and what to fix first
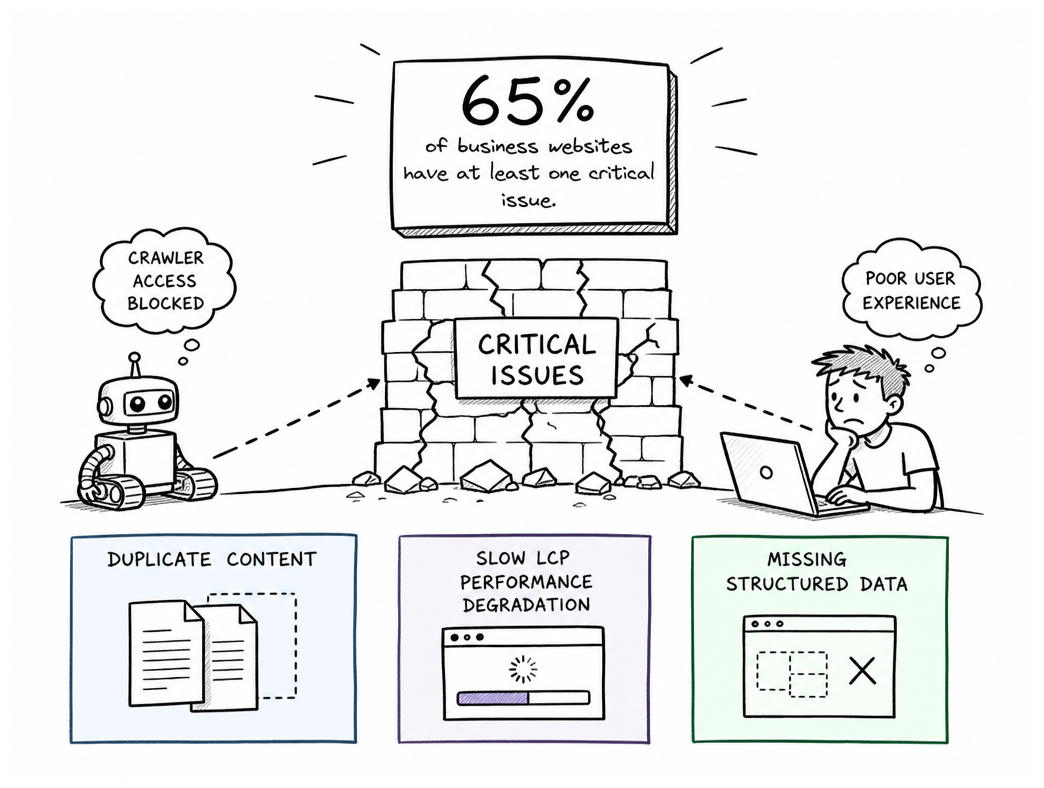
Orphan pages hidden more than 3 clicks away from the homepage aren’t just a crawl budget killer- they confuse search bots and web users alike. Google Search console’s Page Indexing report will show orphan pages so you can find and fix them. Broken links with error 404s and 5xx errors that can disrupt the flow of your crawl and dilute ranking signals. Google Search console’s Crawl Stats report will show if you have broken links and their location by Googlebot type. Involve Digital’s audits have pointed out that 65 percent of business sites have at least one crawlability-related critical problem on it — like duplicate content, slow LCP, or lack of structured data. Heavy AI bot traffic can wreck your Core Web Vitals and not even involve a single Googlebot; traffic crawlers can be gated in robots.txt and not Googlebot. Fixing crawlability issues will improve user experience and metrics like bounce rate and page speed of real web users.
Fixes that work
Orphan pages. An orphan page is any page on your site that does not have at least one inbound link from another page on your site. Run the Page Indexing report within GSC and identify URLs that are not indexed and then link to them within three clicks of your homepage.
Broken links on your site. Every month, review the Crawl Stats report, which breaks down every detected 404 and 5xx error by the type of crawler that detected the error. Fix or redirect pages that the most common crawlers hit first.
Bot overload. Keep an eye on Core Web Vitals in GSC. If LCP is tanking during peak bot traffic, add a crawl-delay or User-Agent rule in robots.txt to throttle non-essential AI crawlers.
Doing this means your content is crawlable. Whether markup then adds anything meaningful is a separate, smaller question.
Schema Doesn’t Need To Be Over-Engineered — Content Structure Will Do the Heavy Lifting
For example, schema markup isn’t the primary lever for AEO and AI citability — content structure is. An H2 with a direct answer will outshine a page optimized with schema and filled with vague LLM friendly prose, every time. While it’s useful to have schema (like Article, BreadcrumbList, and Organization schema), it’s just supporting sigal not foundation. Google’s guidance also suggests you don’t need to fragment content for AI and you should just write for humans and the markup will follow.
“Reality is that AI is really good at getting structure and doesn’t necessarily give priority to the pages that markup”
— Abhishek Iyer, founder of ACME.BOT
What really moves the needle is clear headings that explicitly name concepts, answering immediately in the first sentence, and repeating a labeling pattern across all your pages. AI really extracts prose and the heading hierarchy, not JSON-LD decorations. Write one structure for two audiences: humans skimming and AI extracting cleanly from the same page.
Keep Your Eye on What Actually Moves The Needle: GSC, Core Web Vitals, and Fan-Out Visibility
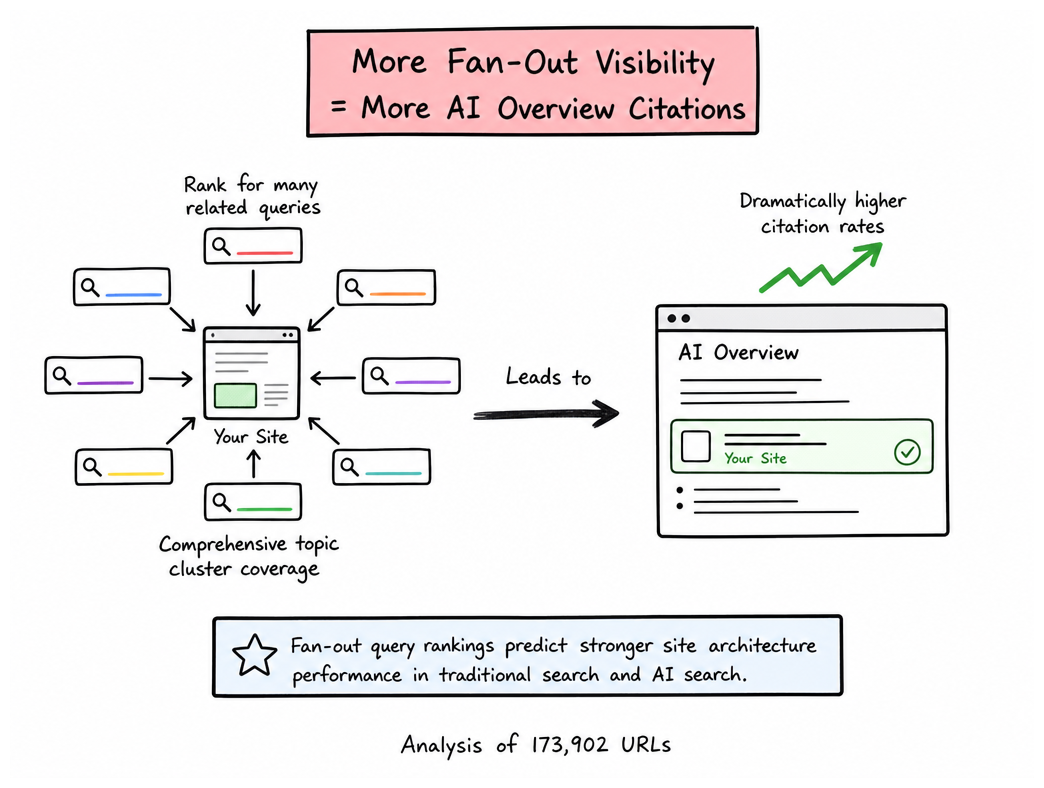
With Google Search Console’s new Generative AI performance reports, you can see URL impressions in your AI features, the first direct signal of AI search traffic. Google-Extended or third-party AI crawlers are not recorded in Crawl Stats, which only tracks Googlebot. Core Web Vitals are still important: Overloading a bot enough to damage LCP is still an indirect technical SEO risk. And you still need traditional rank tracking – if you don’t get a page to rank in Universal Search, you don’t get an opportunity for AI citation.
| Signal | What It Measures | AI Relevance |
|---|---|---|
| GSC Generative AI reports | URL impressions in AI features | Direct AI citation visibility |
| Fan-out query coverage | Multiple queries per topic cluster | Sites ranking for multiple fan-outs are dramatically more cited in AI Overviews |
| Traditional search rankings | Page position in organic results | Prerequisite for AI citation |
When ACME.BOT audits site architecture, they make sure to connect topics cluster gaps with rank-tracking gaps, as well as GSC impressions data. If a page’s rank is climbing but it’s not receiving impressions from AI, it tells ACME.BOT that the page architecture is the issue, not the content of the page – the clusters are wired incorrectly.